

The most effective approach to odkrivanje anomalij v proizvodnji is real-time monitoring tightly integrated with a Manufacturing Execution System, using hybrid statistical and machine-learning models validated against ISO 22400 KPIs. Teams that report F1 and AUC scores alongside OEE and first-pass yield move faster from pilot to production, because an MES gives the data capture and dashboards that modelling alone cannot.
TL;DR:
- Anomaly detection models should be chosen based on data volume, labeling resources, and latency needs, ranging from control charts to transfer learning approaches.
- Proper sensor data collection requires accurate timestamping and product linkage, with noise filtering and feature extraction key to reliable models.
- Deployment challenges include noise robustness, threshold calibration, scheduled retraining, and seamless MES integration for effective real-time actions.
- Model effectiveness is best measured through KPIs like F1 score, AUC, OEE, and scrap ratios, with a focus on translating detection into operational improvements.
- Starting with high-impact, high-frequency lines and involving operators early accelerates progress and enhances threshold tuning accuracy.
Not every irregular reading deserves an alarm, and not every alarm deserves a supervisor’s attention. Point anomalies are single out-of-range readings, a torque spike on one cycle, a temperature dip on a single part. Contextual anomalies only look wrong given the surrounding conditions: a vibration level that is normal at full speed but abnormal during a slow-start sequence. Collective or batch anomalies appear across a sequence of parts, often tool wear creeping in over hundreds of cycles or a material-batch drift that shows up gradually rather than as a single spike.
Which type matters most depends on your line:
Point anomalies demand real-time detection when they signal safety risks or scrap, such as a press overload.
Contextual anomalies need models that understand machine state, not just raw thresholds.
Batch anomalies are often better caught with periodic statistical review than instant alerts, since a single late part rarely proves a trend.
Recipe errors sit in their own category. A changeover that silently reverts to the wrong parameter set behaves like a sudden step change rather than drift, and it needs a different detection strategy again.
Anomaly models are only as good as the signals feeding them. Most production lines already generate usable data: vibration, current and torque, temperature, pressure, cycle time and, increasingly, images from inline cameras. The question is rarely whether a sensor exists, but whether its readings are timestamped, serialised to a specific product, and aligned with the machine state at the moment of capture.
ISO/TR 22400-10 ties KPI calculation directly to accurate event logging, so a missing timestamp or an unlinked serial number does not just hurt a model, it breaks the business reporting built on top of it.
Before modelling, expect to spend real effort on:
Pro Tip: Log every sensor dropout as its own event rather than silently filling the gap. A pattern of dropouts is often an early warning in itself.
There is no single best model, only the model that fits your data volume, labelling budget and latency requirements.
Models that perform well on historical data often struggle once deployed, mainly because production conditions shift and noise behaves differently line to line.
Physically-informed Bayesian feature optimisation shows that semi-supervised monitoring built on these principles stays robust to hyperparameter changes, which matters when a line rarely sits still long enough for perfect tuning.
A model’s performance only matters once it is translated into terms a plant manager already tracks. Precision tells you how many flagged anomalies were real; recall tells you how many real anomalies you caught; F1 balances the two when both false alarms and missed defects carry a cost; AUC summarises performance across thresholds.
Advanced process anomaly-detection models have reached F1 scores of 0.96 to 1.0 in controlled industrial experiments on repetitive processes, with transfer-learning frameworks reporting F1 increases of roughly 25 to 26% over baseline methods in multi-condition monitoring. Numbers like these only mean something when mapped to OEE, first-pass yield and scrap ratios, the elements ISO 22400 defines for Manufacturing Operations Management. A short pilot should report both sets of figures side by side: model metrics and business KPIs, so a decision-maker can judge impact without needing to interpret a confusion matrix.

A model that flags an anomaly in isolation changes nothing. The value appears once detection connects to a system operators already use. A practical architecture runs edge capture into lightweight inference, then streams events into an MES for central analysis and dashboarding.
A capable MES for this purpose needs to offer:
Closing that loop shortens the gap between a detected deviation and a corrective action, and it removes a layer of manual transcription that tends to introduce its own errors.
Start on the highest-frequency, highest-impact line you have, with a control chart or a normal-only model rather than a complex classifier you cannot yet validate. Bring operators in from day one: their judgement on false alarms shapes thresholds faster than any amount of offline tuning. Treat the first deployment as one iteration among several, not a finished system.
— Andraž
Once a detection approach proves itself, the harder problem is usually operational: getting flagged events in front of the right person, on the right machine, fast enough to matter. Mestric™ MES connects directly to shop-floor equipment and captures timestamped data automatically, so the traceability that anomaly detection and ISO-aligned KPI reporting both depend on is already in place rather than bolted on afterwards.
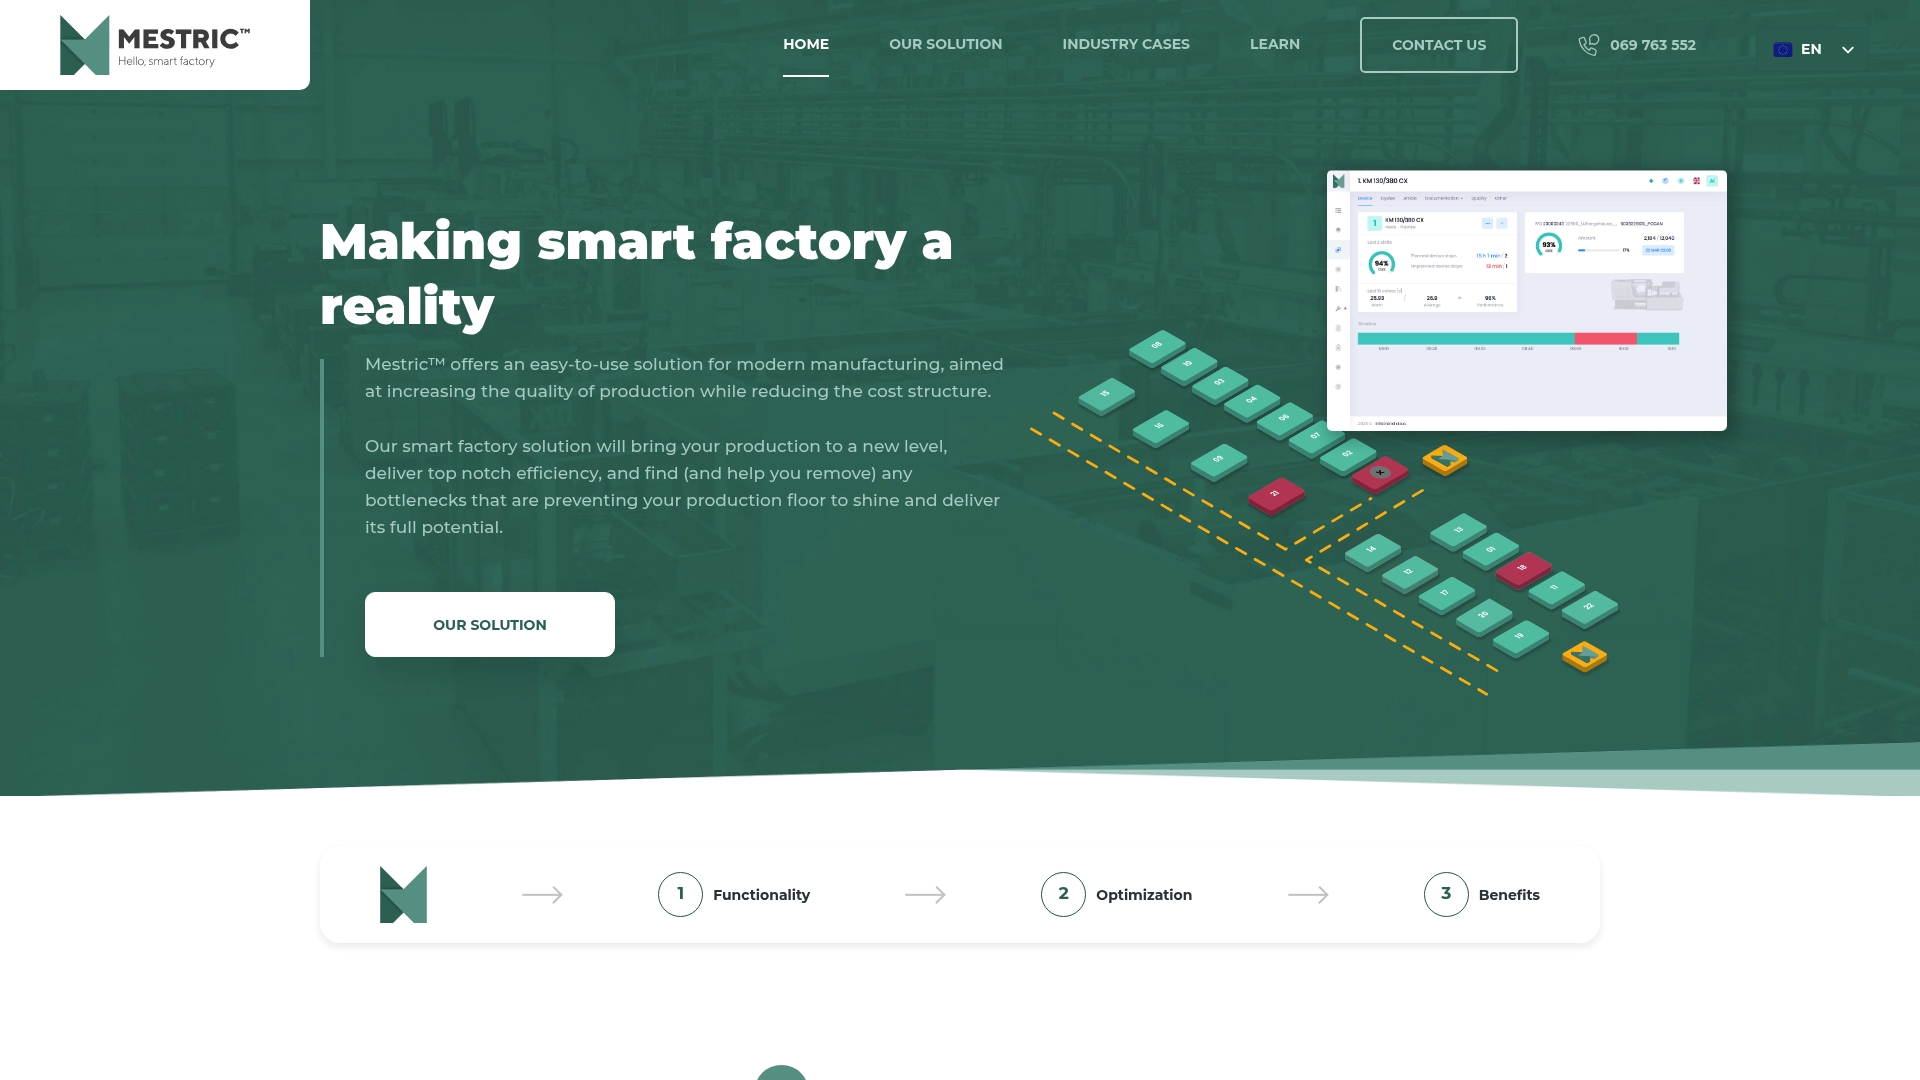
Live KPI dashboards bring detection events into the same view as OEE, downtime and quality figures, which shortens the path from a flagged deviation to a corrective action on the floor. For teams comparing options, our piece on MES against traditional manufacturing approaches lays out where an integrated system earns its place over spreadsheets and standalone sensors.
If you are ready to see how this looks on a real production line, you can request a demonstration of Mestric™.
Real-time detection flags deviations as they happen, which suits safety-critical or high-cost defects where delay is expensive. Batch or post-process inspection reviews data after a run completes, which works well for slower-forming issues like gradual material drift where instant alerts would add noise without adding value.
Vibration, current or torque, temperature, pressure and cycle time cover most mechanical and thermal failure modes, with inline images added where visual defects matter. The right mix depends on your failure history more than on any general rule.
F1 balances false alarms against missed defects, while AUC shows how a model performs across different alert thresholds. Research on knowledge-integrated transfer learning reports an average F1 of 0.9226 and AUC of 0.9353 across working conditions, figures that should be read alongside OEE and scrap-rate changes, not instead of them.
Yes. Recipe-based and transfer-learning methods are built for exactly this problem. Recipe-based adaptable learning in injection moulding detected far more real defects than a generalised model trained without that structure, which makes it a practical route when labelled failures are scarce.
No, it complements it. Detected anomalies, particularly gradual ones like rising vibration or torque drift, help shift maintenance timing from a fixed schedule to one based on actual machine condition, which tends to catch wear before it causes a breakdown.
ISO 22400 defines the KPI framework behind OEE, first-pass yield and MTBF/MTTR calculations used throughout this guide. The VARADE++ paper covers edge-friendly real-time detection, the MDPI Sensors study covers recipe-based learning for injection moulding, and the Applied Sciences benchmark review covers transfer-learning performance across multi-condition factories. For operational controls that sit alongside these KPIs, see this bizSAFE Star implementation guide.


 069 763 552